Cross-Modal Progressive Perspective Matching Network for Remote Sensing Image-Text Retrieval
Progressive geographic-perspective modeling for cross-modal retrieval
IEEE Transactions on Multimedia, 2025
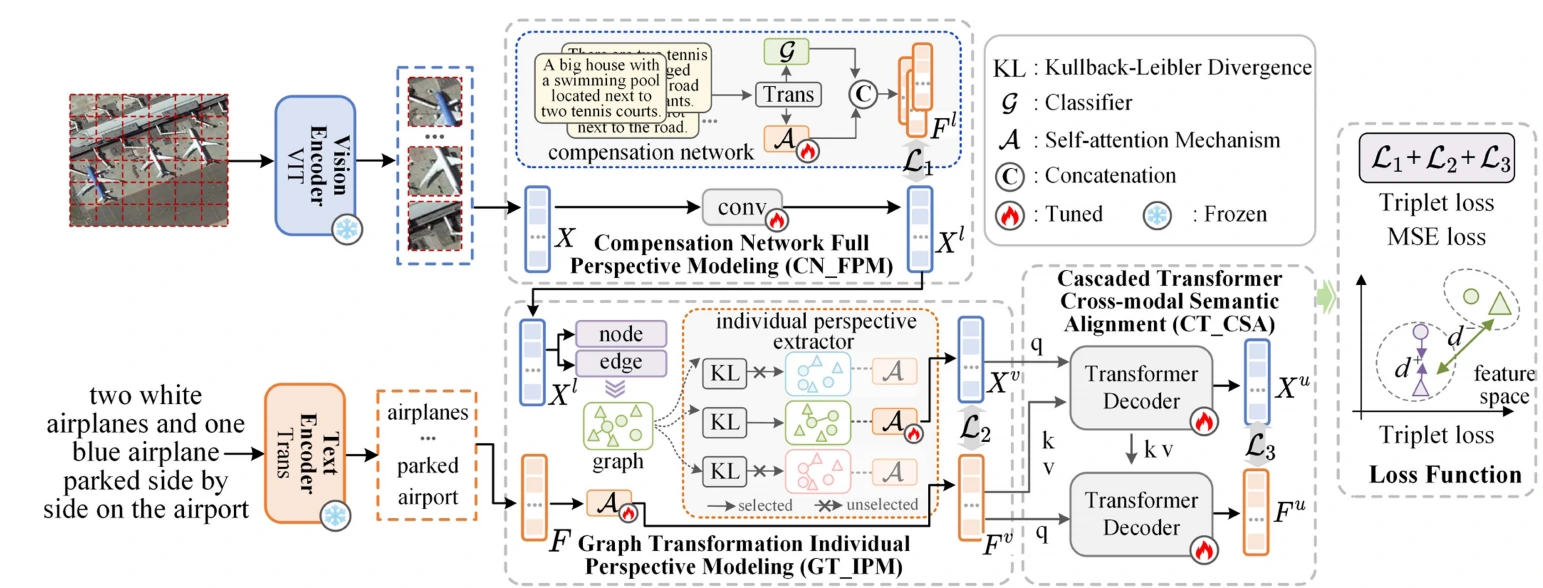
CPPMN method overview supplied by the project author.
I. Overview
Remote-sensing scenes can be described from multiple geographic perspectives. Retrieval systems that collapse those perspectives into one representation may match a query to the wrong region or overlook the relevant spatial relationship.
CPPMN progressively learns full-image perspectives, exposes perspective-specific cross-modal relationships, and then aligns image and language features semantically.
II. Key Contributions
- Uses positive text descriptions to supervise full-perspective visual feature learning.
- Transforms implicit perspective features into explicit cross-modal relationship graphs.
- Applies cascaded Transformer layers for progressive image–text semantic alignment.
III. Methodology
The network combines a compensation module for full-perspective modeling, a graph transformation module for locating individual perspectives, and a cascaded Transformer for cross-modal semantic alignment. Graph density and connectivity help identify the perspective referred to by the query.
IV. Main Findings
Quantitative and qualitative experiments across four remote-sensing image–text retrieval datasets demonstrate the value of progressive perspective matching and semantic alignment.
Reference
Citation
BibTeX citation
@article{zheng2025cross,
  title={Cross-modal progressive perspective matching network for remote sensing image-text retrieval},
  author={Zheng, Chengyu and Li, Xiu and Liang, Xinyue and Huang, Lei and Du, Shan and Nie, Jie and Dong, Junyu},
  journal={IEEE Transactions on Multimedia},
  volume={27},
  pages={3966--3978},
  year={2025},
  publisher={IEEE}
}
Continue exploring
Related Projects
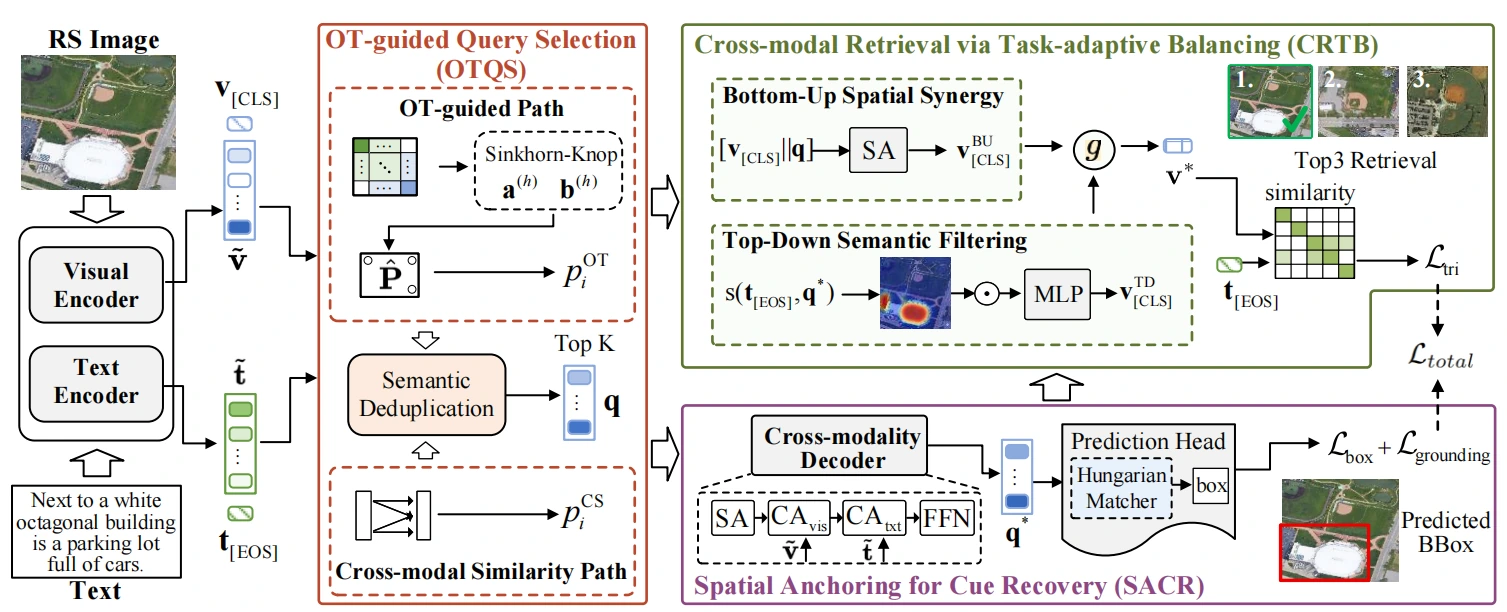
Explicit Spatial Localization and Task-Adaptive Balancing for Remote Sensing Image-Text Retrieval
A remote-sensing image–text retrieval framework that combines explicit object localization with adaptive coordination between spatial and semantic learning objectives.
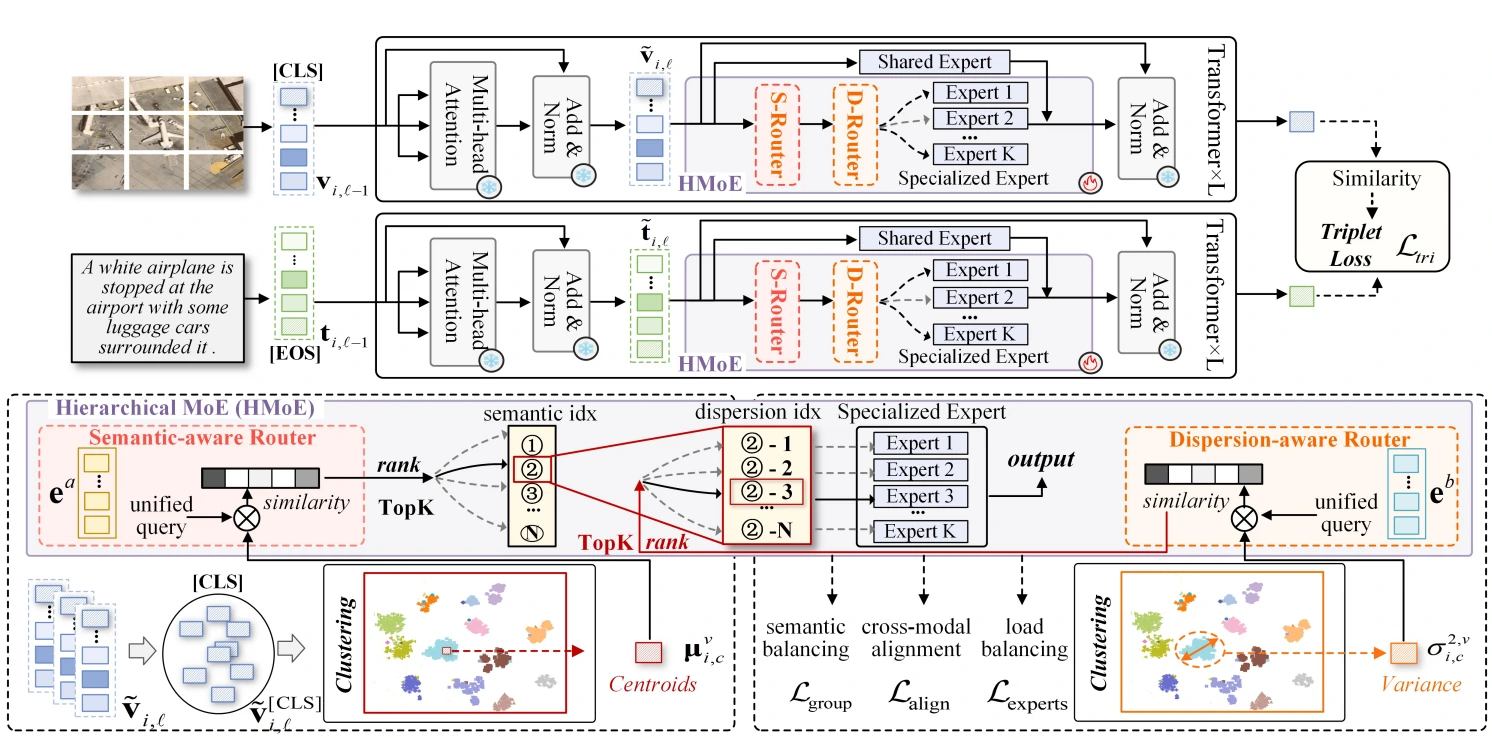
H-MoC: Hierarchical Mixture-of-Experts for Semantic- and Dispersion-Consistency in Remote Sensing Image-Text Retrieval
A hierarchical mixture-of-experts retrieval framework that promotes both semantic consistency and balanced feature dispersion across remote-sensing image and text representations.