Scale–Semantic Joint Decoupling Network for Image-Text Retrieval in Remote Sensing
Separating scale-specific visual cues and shared cross-modal semantics
ACM Transactions on Multimedia Computing, Communications, and Applications, 2023
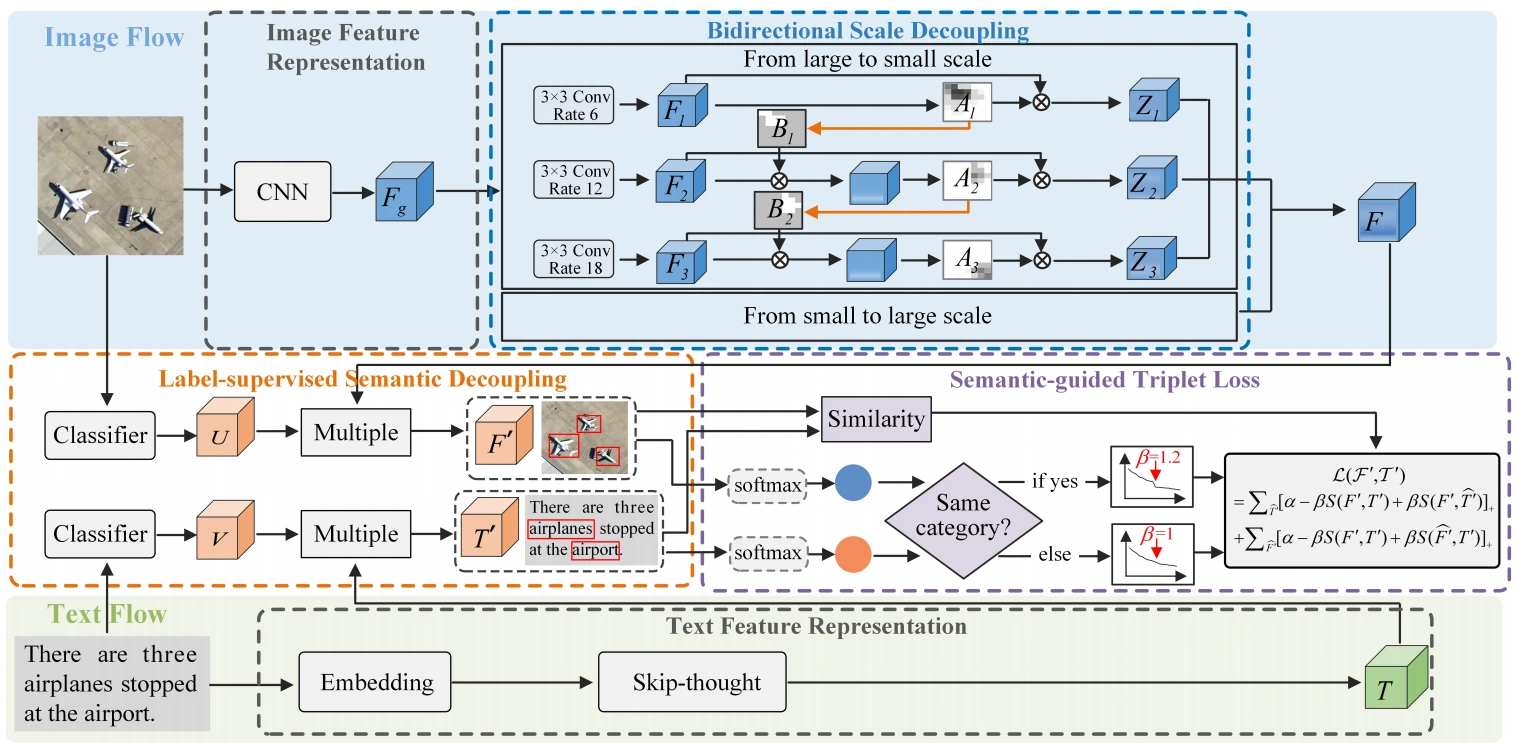
Method overview supplied by the project author.
I. Overview
The visual evidence corresponding to a caption may appear at different scales across remote-sensing images. This project separates scale-sensitive visual structure from shared semantic content and then learns how the two should interact during retrieval.
II. Key Contributions
- Decouples multi-scale visual information to preserve objects at different resolutions.
- Separates semantic components used for image–text alignment.
- Jointly optimizes the scale and semantic representations for bidirectional retrieval.
III. Methodology
Image and text encoders generate modality-specific features. Scale-decoupling modules refine the visual hierarchy, semantic-decoupling modules identify cross-modal concepts, and a joint matching stage combines them in the retrieval embedding space.
IV. Research Focus
The method addresses retrieval settings where global scene appearance is similar across candidates but the caption refers to a structure visible at a particular scale.
Reference
Citation
BibTeX citation
@article{zheng2023scale,
  title={Scale-semantic joint decoupling network for image-text retrieval in remote sensing},
  author={Zheng, Chengyu and Song, Ning and Zhang, Ruoyu and Huang, Lei and Wei, Zhiqiang and Nie, Jie},
  journal={ACM Transactions on Multimedia Computing, Communications and Applications},
  volume={20},
  number={1},
  pages={1--20},
  year={2023},
  publisher={ACM New York, NY}
}
Continue exploring
Related Projects
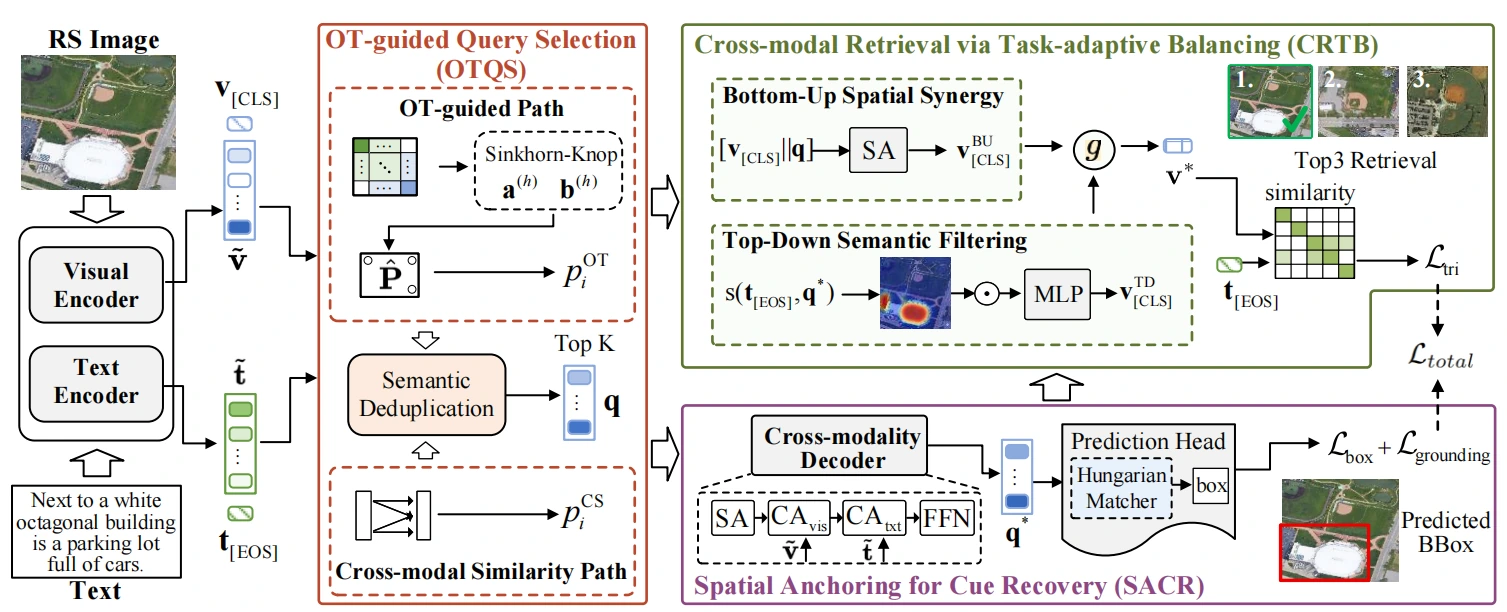
Explicit Spatial Localization and Task-Adaptive Balancing for Remote Sensing Image-Text Retrieval
A remote-sensing image–text retrieval framework that combines explicit object localization with adaptive coordination between spatial and semantic learning objectives.
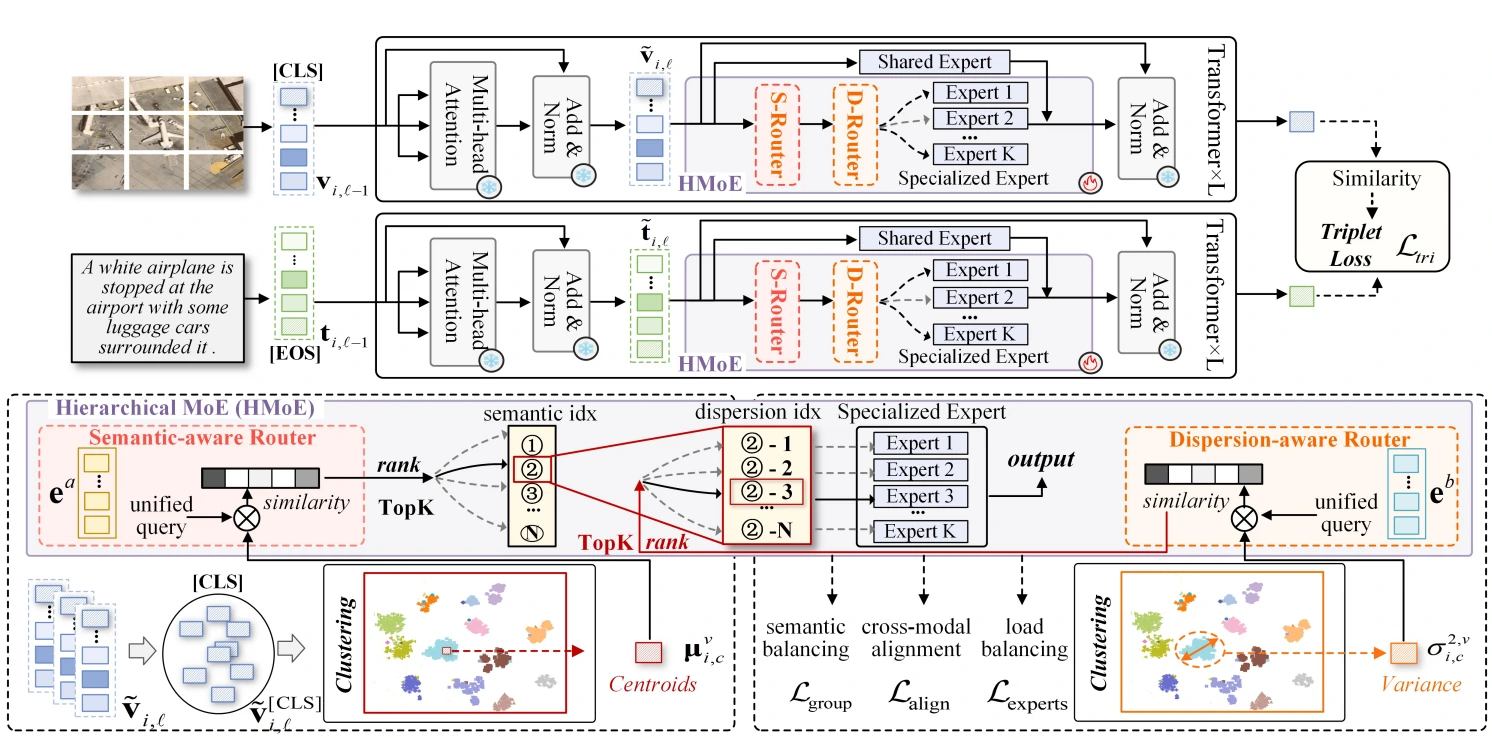
H-MoC: Hierarchical Mixture-of-Experts for Semantic- and Dispersion-Consistency in Remote Sensing Image-Text Retrieval
A hierarchical mixture-of-experts retrieval framework that promotes both semantic consistency and balanced feature dispersion across remote-sensing image and text representations.